Omniroute: Low-Latency Multi-Model AI Gateway with Semantic Caching
Designed a sub-15ms AI model proxy normalizing OpenAI and Anthropic requests with real-time health checks, Redis semantic caching, and dynamic token routing.
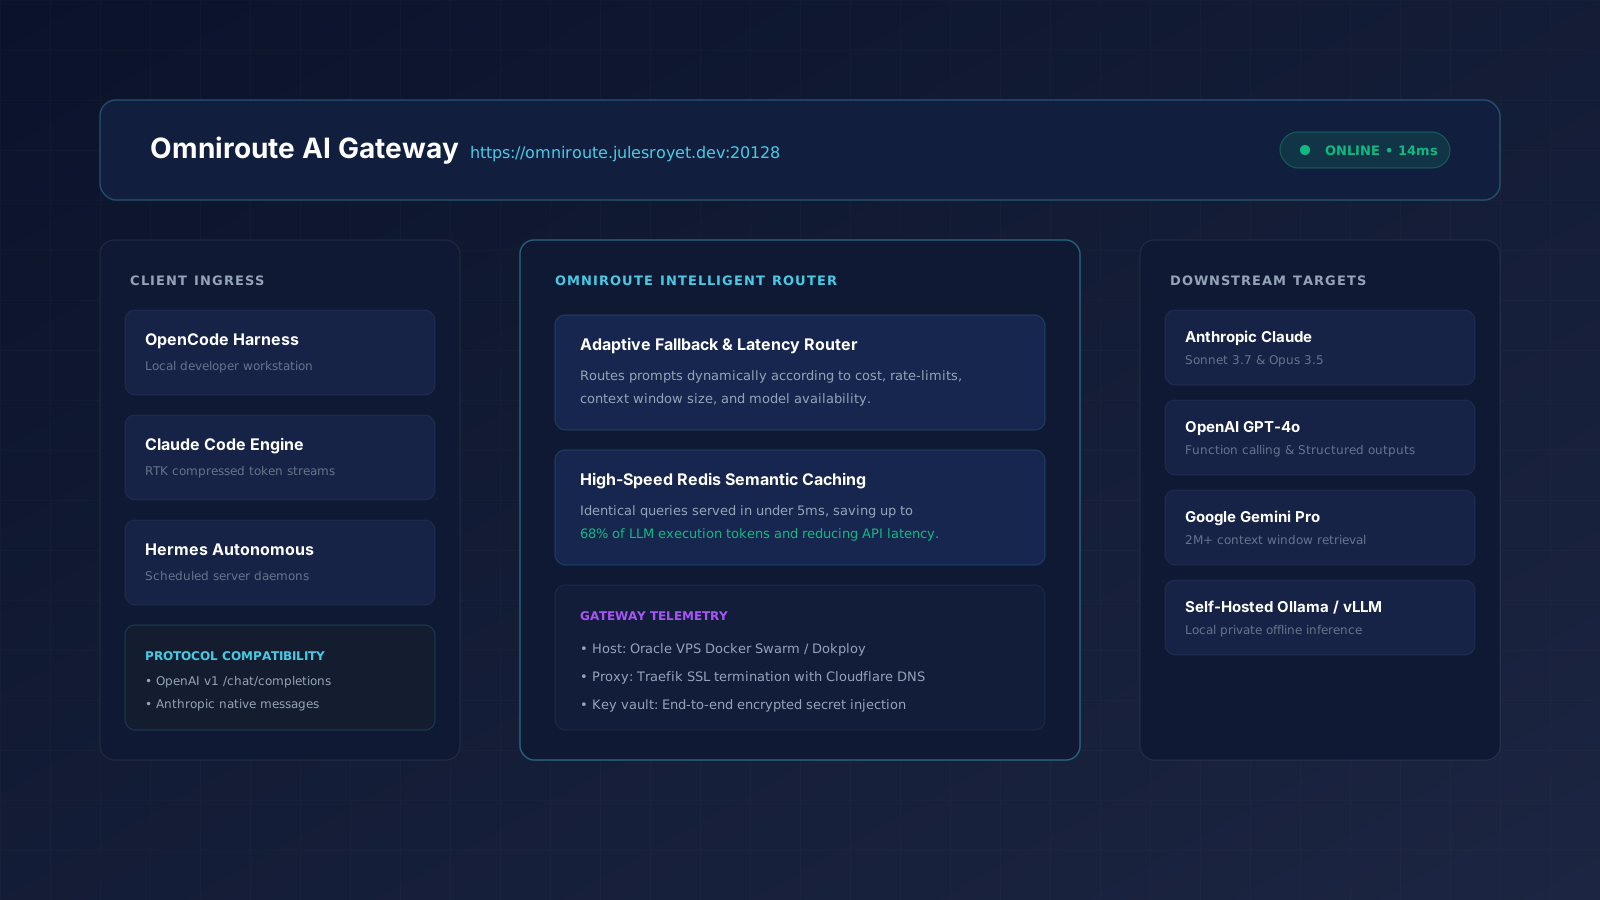
The Challenge: Eliminating Provider Outages and Redundant LLM Invocations
Applications relying directly on upstream LLM APIs face frequent latency spikes, rate limits, and breaking schema differences. Omniroute was designed as a unified ingress layer that normalizes schemas, caches identical or semantically similar prompts in Redis, and automatically falls back to secondary models if latency exceeds thresholds.
Streaming Edge Architecture
Incoming requests arrive via Cloudflare Edge with SSL termination and rate-limiting. A Node.js streaming proxy parses token streams chunk by chunk with zero buffer allocation, calculating real-time TTFT (Time to First Token) and storing normalized vector hashes in Redis.
Key Engineering Challenges
- Maintaining Server-Sent Events (SSE) stream integrity while calculating token consumption in-flight.
- Semantic cache invalidation strategies based on temperature and query randomness.